Short Answer
In the world of data analysis, extracting the top values from a dataset is a fundamental task. With the Pandas library, this process is both straightforward and incredibly powerful, making it a favorite among analysts and scientists alike. The fascination with obtaining the top 10 values goes beyond mere curiosity; it often reveals trends, outliers, and critical insights that drive decision-making. Below is a step-by-step guide on how to get top 10 values in Pandas, addressing common scenarios and some nuanced techniques that expand your data manipulation toolkit.
1. Use the .nlargest() Method
The most direct way to get the top 10 values from a DataFrame or Series is by using the nlargest() method. It is efficient and optimized for this purpose. For example, df['column'].nlargest(10) returns the top 10 entries from a specific column, sorted in descending order.
2. Applying .nlargest() on Multiple Columns
Pandas allows selecting multiple columns for nlargest by chaining or specifying it on a DataFrame. When dealing with multiple columns, you can sort by one primary column but still retrieve the entire row, which offers a comprehensive look at those top entries.
3. Using .sort_values() With Head()
Another common approach is to sort values in descending order using sort_values() and then pick the top 10 using head(10). For instance, df.sort_values('column', ascending=False).head(10) achieves the same result but is more flexible for custom sorting.
4. Handling Ties with nlargest
When multiple entries share the same value at the cutoff, nlargest() may return only the first occurrences. For strict control over ties, sorting with sort_values() provides a more deterministic output where you can explicitly handle or display ties.
5. Extracting Top 10 Rows from Entire DataFrame
To get the top 10 rows of a DataFrame based on a single column, combining sort_values() and head() is typically used. This approach retrieves all columns but ranks rows by the specified column’s value.
6. Working with Multiple Criteria
Sometimes top values depend on more than one column, like top sales and then top profits. You can sort by multiple columns using sort_values(by=['sales', 'profit'], ascending=[False, False]) and then use head(10) to get the highest-ranking rows across criteria.
7. Using Query with nlargest for Conditional Top 10
If the top 10 values must meet certain conditions, you can first filter the DataFrame using query() or Boolean indexing, then apply nlargest(). This allows for targeted extraction of significant data points under specific scenarios.
8. Retrieving Top 10 Index Values Only
To extract just the indices of the top 10 entries (for example, row labels), apply nlargest() to your column and use the .index attribute. This technique is particularly useful when you need to reference the results without the whole data payload.
9. Using .rank() to Get a Ranking Column
Create a new column that ranks your data using the rank() method. Then filter rows where rank is within the top 10. Ranking provides a relative position within the data that can be easily queried or visualized.
10. Handling Missing Values Before Top 10 Extraction
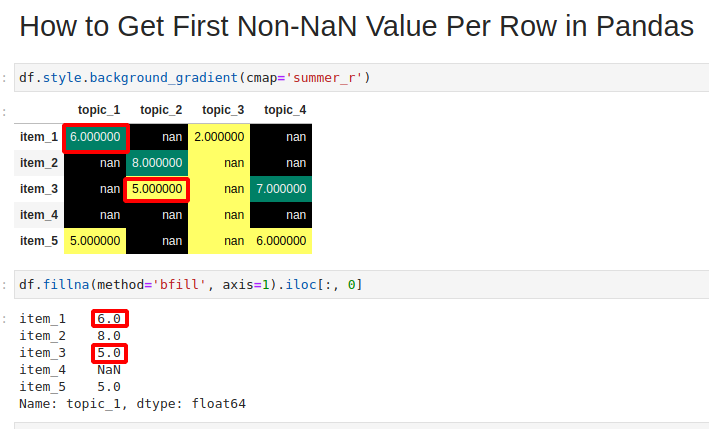
Missing or NaN values can affect the ranking or sorting process. It’s good practice to handle them using dropna() or fill them with a placeholder value before extracting top 10 values to maintain accuracy in results.
11. Performance Considerations with Large Datasets
For very large datasets, nlargest() is typically faster than sorting and slicing because it uses an optimized algorithm. When speed is critical, prefer nlargest(), especially if you’re only interested in the top N values from a column.
12. Leveraging GroupBy with nlargest()
To find the top 10 values within subgroups of data, combine groupby() with nlargest(). For example, df.groupby('category')['value'].nlargest(10) returns the highest values per group, uncovering intra-category leaders.
13. Resetting Index After Extraction
After obtaining the top 10 values, indexes might be non-sequential. Use reset_index(drop=True) to clean up the DataFrame index, which is helpful when preparing data for reporting or downstream processes.
14. Visualizing Top 10 Values
Once top 10 values are extracted, you can use visualization libraries like Matplotlib or Seaborn to graphically represent the data. Visual insights reinforce numeric outputs and help identify trends and patterns at a glance.
15. Exporting Top 10 Values
Often, extracted top 10 data needs to be shared or further analyzed. Use to_csv() or to_excel() to export the subset, facilitating collaboration and integration with other tools.
16. Using .tail() for Bottom 10 Values
Understanding the process of getting the top 10 values also opens the door for getting the bottom 10 using nsmallest() or sorting ascending and applying head(10). This symmetry is useful in identifying underperformers or low extremes.
Mastering these methods provides a strong foundation for deeper data analysis. Extracting top 10 values is more than a basic operation; it’s a gateway to understanding data distributions, prioritizing focus areas, and making informed decisions grounded in numerical evidence.
FAQ
What is the easiest way to get the top 10 values in Pandas?
The easiest way is to use the nlargest() method on a DataFrame or Series, for example, df['column'].nlargest(10).
How can I handle ties when extracting the top 10 values?
Using sort_values() followed by head() provides more control over ties compared to nlargest(), which returns only the first occurrences.
Can I get top 10 values based on multiple columns?
Yes, you can sort by multiple columns using sort_values(by=['col1', 'col2'], ascending=[False, False]) and then use head(10) to extract the top rows.
How do I extract top 10 values within groups in Pandas?
You can combine groupby() with nlargest(), e.g., df.groupby('category')['value'].nlargest(10), to get top values per group.
How to handle missing values before extracting top 10?
It's recommended to handle missing values with dropna() or fillna() to prevent them from affecting sorting or ranking.
Leave a Reply